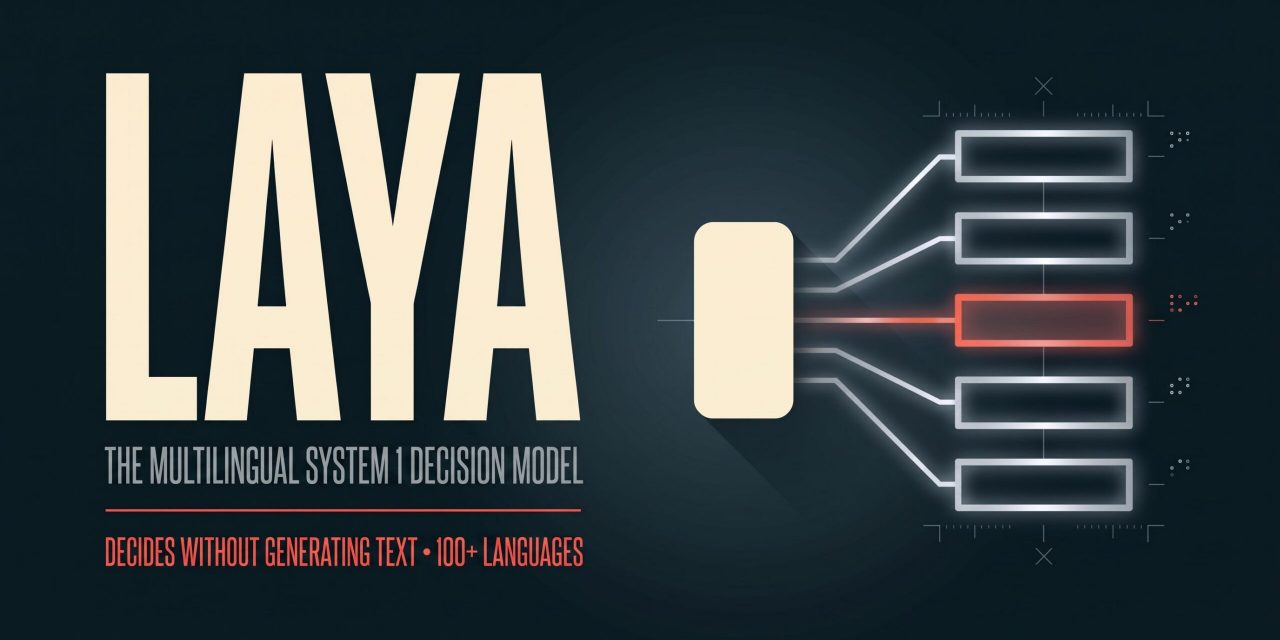
Routing a support ticket or flagging a phishing email requires a single answer. Most teams still get that answer by prompting a generative LLM, waiting half a second or more, and parsing a JSON string that may or may not be valid. Laya, an open decision model from Convai Innovations, handles this job differently. You give it a state and a set of typed questions. It returns typed answers with probabilities in one forward pass. It never generates text.
This article explains how the Laya AI model works, which checkpoint to pick, what the published benchmarks show when you read them carefully, and how to evaluate it on your own workflow before you trust it with real decisions.
What the Laya decision model does
Laya is a multilingual, non-autoregressive System 1 decision model. The System 1 label comes from the distinction between fast, reflexive judgment and slow, deliberate reasoning as described by Daniel Kahneman in his book Thinking Fast and Slow. A generative LLM writes answers token by token, which suits drafting and explanation. Laya reads the entire input at once with a bidirectional encoder and scores a fixed set of answers you define in advance.
The input is a state, which can be a ticket, an email, a chat transcript or a JSON document, plus one or more questions. The output is an answer object with a value and a probability distribution for each question. Code and weights are released under Apache 2.0, so you can run Laya locally, air gapped if needed, and finetune it on your own data.
Because the answer space is fixed before inference, Laya can’t invent a category or return malformed output. It can still be wrong. For that reason, the probabilities it reports carry more weight than the “can’t hallucinate” slogan.
Choice, score and noul, the three question types
Every Laya request uses one or more of three primitives:
- Choice selects one option from a named set, such as billing, technical, sales or other. It suits department routing, intent classification and topic tagging.
- Score places the state on an ordered rubric, such as routine, soon and blocking. It returns a distribution over levels and an expected score, which is useful for urgency, frustration or harm severity.
- Noul estimates the probability that a proposition is true. “Does the customer explicitly threaten to cancel?” returns P(true) between 0.0 and 1.0. Typical uses include spam filtering, jailbreak detection and churn risk.
A useful habit is to separate prediction from action. A high churn probability can open a review task. It should never issue a refund on its own. The model’s decision feeds your policy and leaves the policy itself to you.
How Laya works under the hood
The English checkpoint combines a ModernBERT-large encoder with a decision head trained from scratch, for about 421M parameters in total. The multilingual checkpoint uses mmBERT-base with a 256k vocabulary and roughly 322M parameters. Each answer option gets its own [MASK] token. The model reads the hidden state at that marker, produces a logit, and applies a softmax over the options of that question. New schemas therefore need no retraining. You simply pass different options.
Calibration comes from the training method, which Convai calls RLCD, short for reinforcement learning for calibrated decisions. The reward is a strictly proper scoring rule, so the model maximises its expected reward only by reporting honest probabilities. Builder Nandakishor Mukkunnoth summarises the problem it solves bluntly: “Naive RL maximizes accuracy by destroying calibration. It turns your model into a confidently wrong machine.”
Three checkpoints and a Router
Laya is a family of three checkpoints hosted in one Hugging Face repository:
- laya, the English root, for English triage, guardrails and email classification.
- laya-multilingual, for 100+ languages and mixed-language traffic, about 2.2 times faster than the English model.
- laya-typed-decisions, finetuned on four specific workflows: invoice processing, security incidents, customer service and agent trace observability.
The built-in Router detects script and language in under half a millisecond and dispatches each request to the right checkpoint. This matters because the English checkpoint fails badly outside Latin scripts. On Khmer, it scored 0.000 accuracy while reporting 0.952 confidence. Confidence gating can’t catch that failure, so the routing decision has to happen before the forward pass.
Very short Latin-script messages such as “Quero cancelar” carry little language signal and default to English. If most of your traffic is non-English, set the Router default to multilingual or pass your own language detection through lang_guess.
Speed and deployment options
On a Tesla T4, Laya answers a single question in about 33 ms and handles batched questions at around 7.2 ms each.
Reading the Laya benchmarks honestly
The headline figure says Laya scores 0.766 accuracy on a 2,000-decision typed benchmark, ahead of Jev’s published 0.727. That number belongs to the finetuned typed-decisions checkpoint. The base English and multilingual checkpoints score 0.362 and 0.352 on the same set, close to the 0.318 random baseline and below the 0.461 majority-class baseline. Laya is a fast base to specialise, and you shouldn’t treat it as a zero-shot oracle.
Other limits documented by the maintainers themselves:
- Large label sets degrade quickly. Options share a fixed token budget, so on Banking77 with 77 labels each option gets only 3 to 4 tokens and accuracy drops to 0.425, against 0.870 for Jev. Raising
head_max_len, shortlisting with embeddings or splitting into a coarse and a fine question can help. - Score questions are the weakest primitive, with 0.372 on SST-5. The multilingual checkpoint also rarely picks the first-listed level.
- Noul on the English checkpoint can follow its default true/false labels instead of the input. Adding explicit criteria or using a two-option choice with neutral keys such as A and B works around this.
- Negation remains fragile. In a small cancellation test, negated requests were still classified as cancel_account.
- Calibration ships over-confident. Refitting one temperature per question type and option count on held-out data brings mean ECE from 0.466 to 0.081 for the English model. The multilingual checkpoint ships with no fitted temperatures at all.
Where Laya performs well out of the box, it performs very well. Spam filtering reaches 0.993 and phishing detection 0.980. Binary safety calls are its strongest territory, while wide and fuzzy classification tasks call for finetuning.
How to evaluate Laya on your own workflow
Start with a question a human can label consistently. Write down the input, the allowed answers, label definitions and the action each answer may trigger. Let two people label a sample independently and fix the rubric wherever they disagree.
Build a test set that includes short messages, typos, code switching, quoted irrelevant text and contradictory evidence. Then measure:
- a confusion matrix plus precision and recall for each label, especially rare or costly ones;
- errors between adjacent score levels;
- a reliability diagram and ECE after temperature fitting on validation data, keeping the final test set untouched;
- selective accuracy at a chosen coverage, using the built-in
min_confidenceoption to send uncertain cases to a human; - p50 and p95 latency under realistic concurrency on the exact checkpoint and device you plan to deploy.
Report results per language and per input length, since a pooled average can hide a weak group. Run Laya in shadow mode next to your current process before it takes any action. The laya.evals module can gate CI builds on these metrics, so a quality change after an upgrade shows up as a reviewable diff.
If the baseline shows a consistent gap and you have clean labels, the official finetuning notebook runs the full loop on Kaggle’s free dual T4 GPUs in about four to five hours. A community example shows the potential: a browser agent head improved from 0.10 to 0.66 top-1 element accuracy after specialisation.
Where Laya earns its place
Laya suits teams that want local inference, strict data locality and ownership of the model, and that have a few hundred domain labels to spend on finetuning. Teams that need broad zero-shot accuracy or dozens of labels per question without extra work will find a hosted option like Jev easier to start with. The more useful shift lies in how you design the task. Writing a tight rubric and a labelled test set before choosing any model forces you to define what a correct decision is. That definition keeps its value when you switch between Laya, Jev or whatever model comes next.